- Previous best
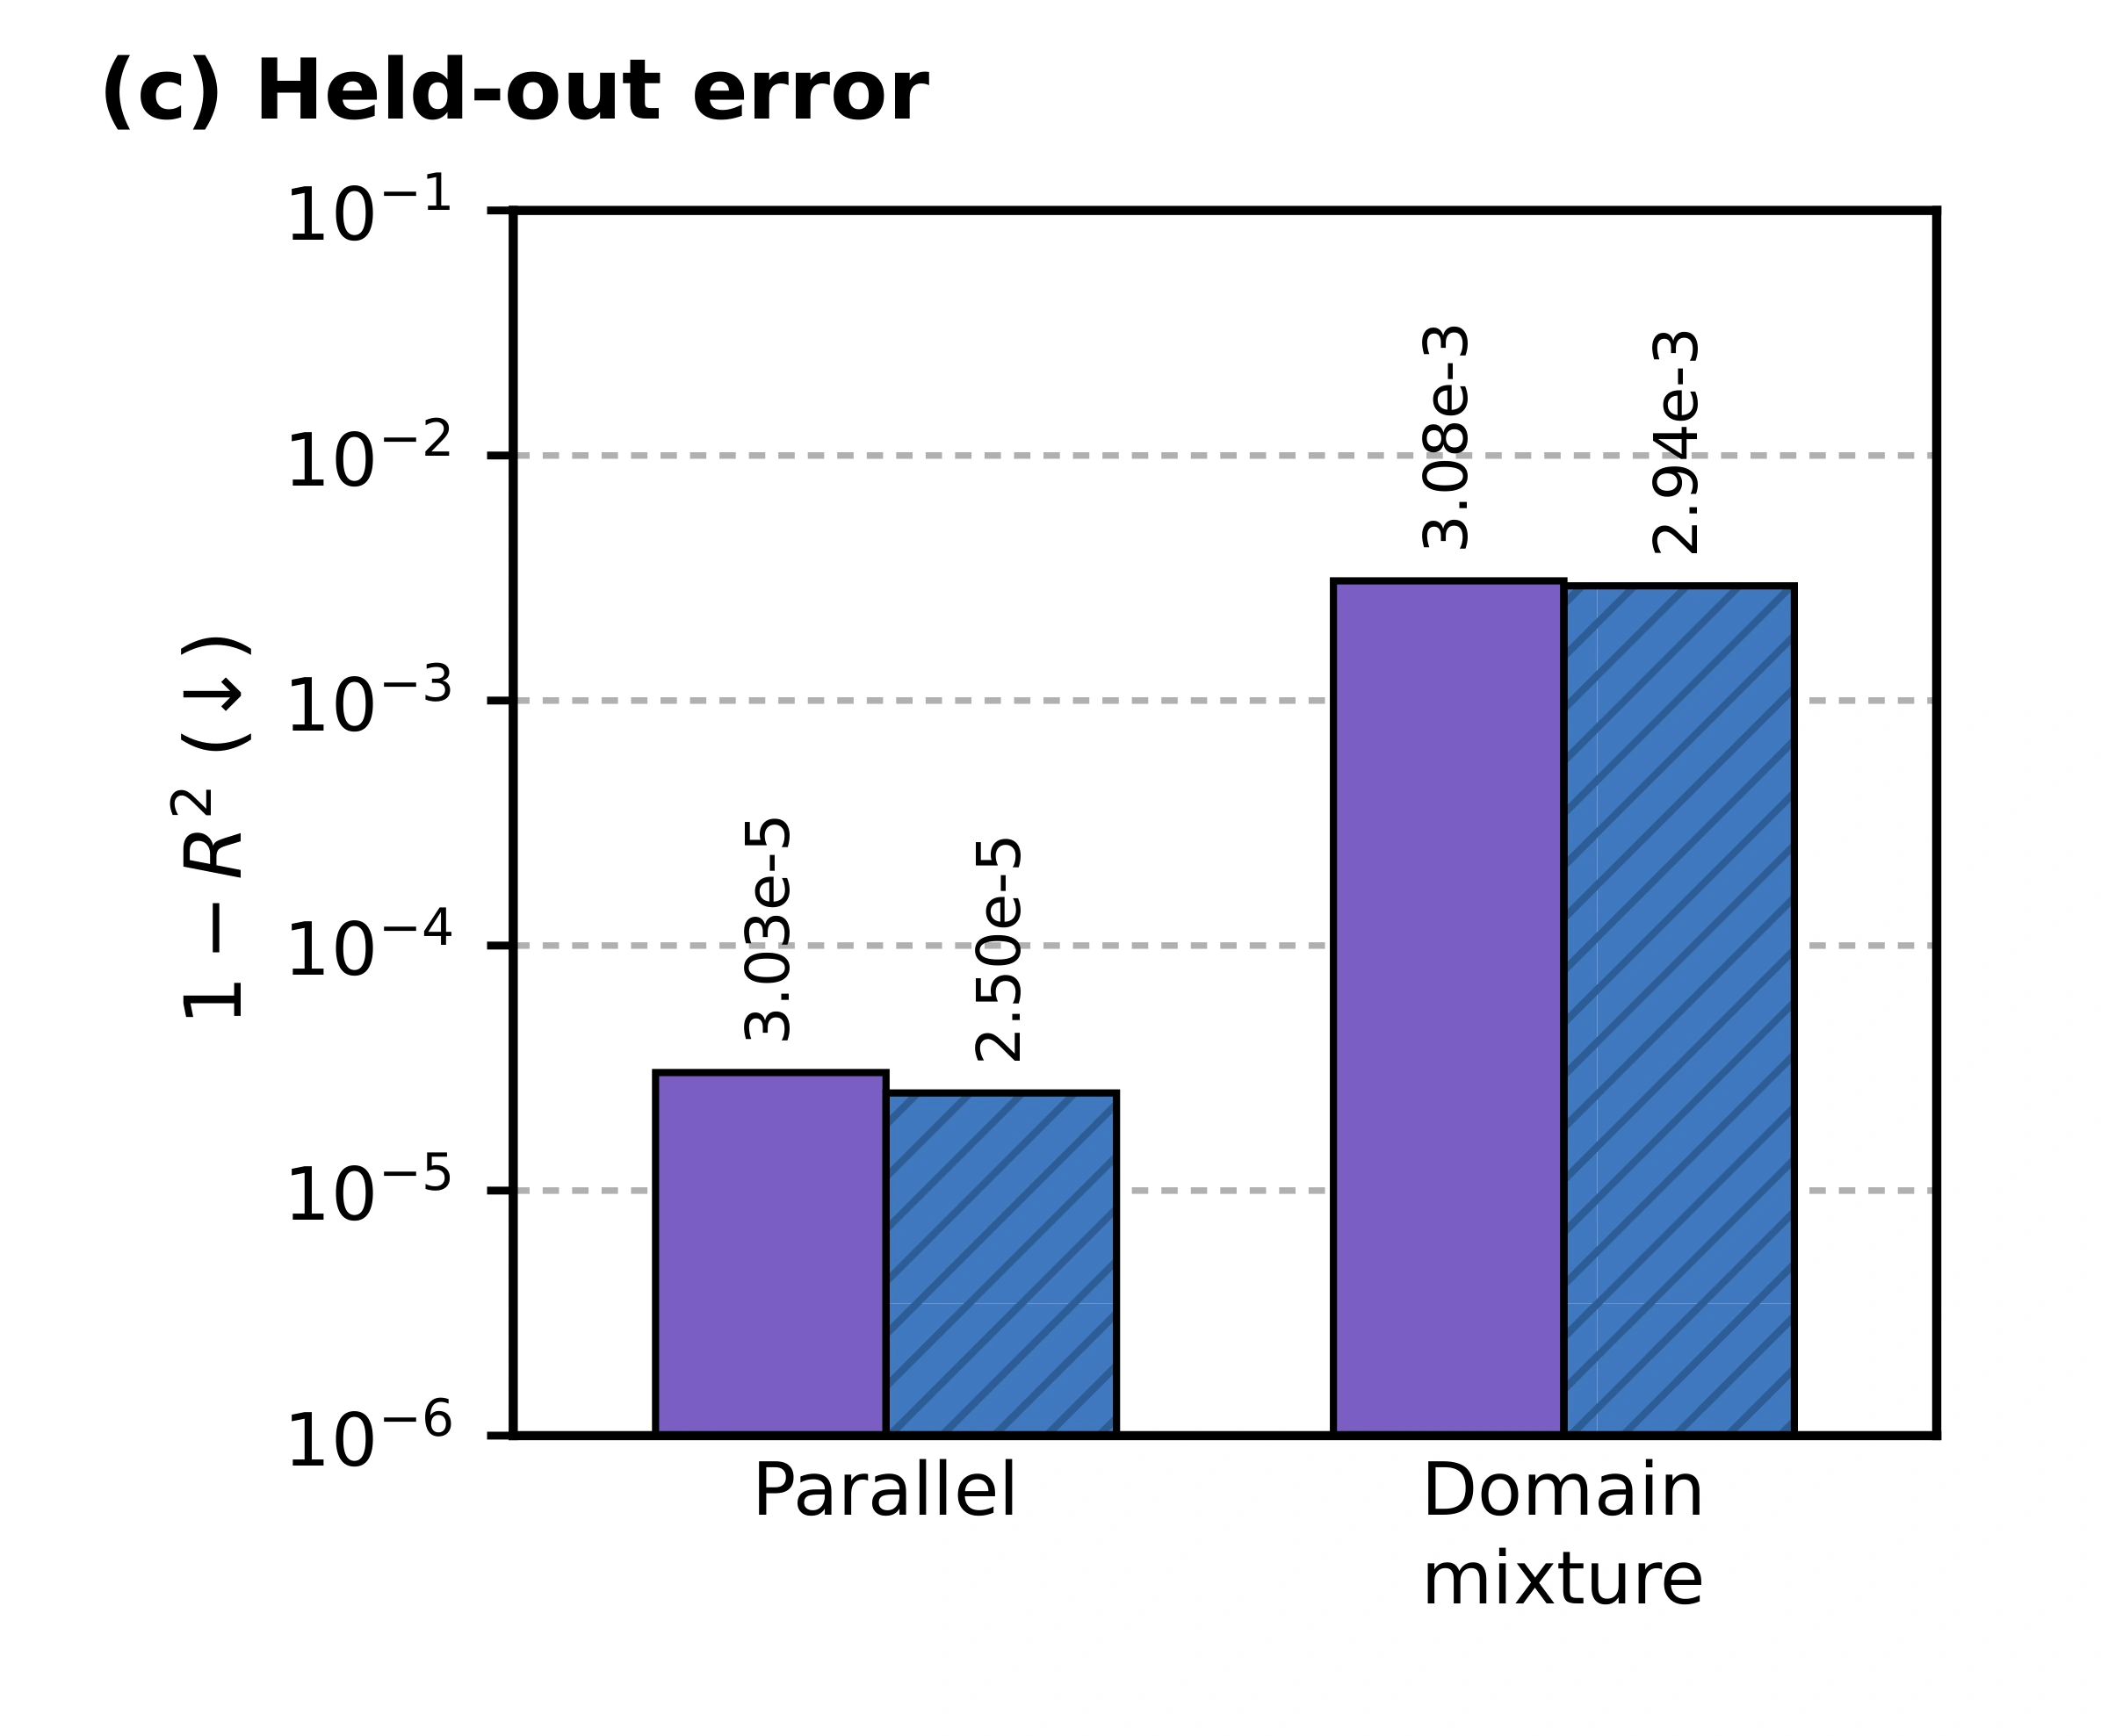
- 0.999970
- EvoDuet
- 0.999975
- Objective
- Held-out R² ↑
- Run cost
- $11.93
Source
Python
# EVOLVE-BLOCK-START
"""
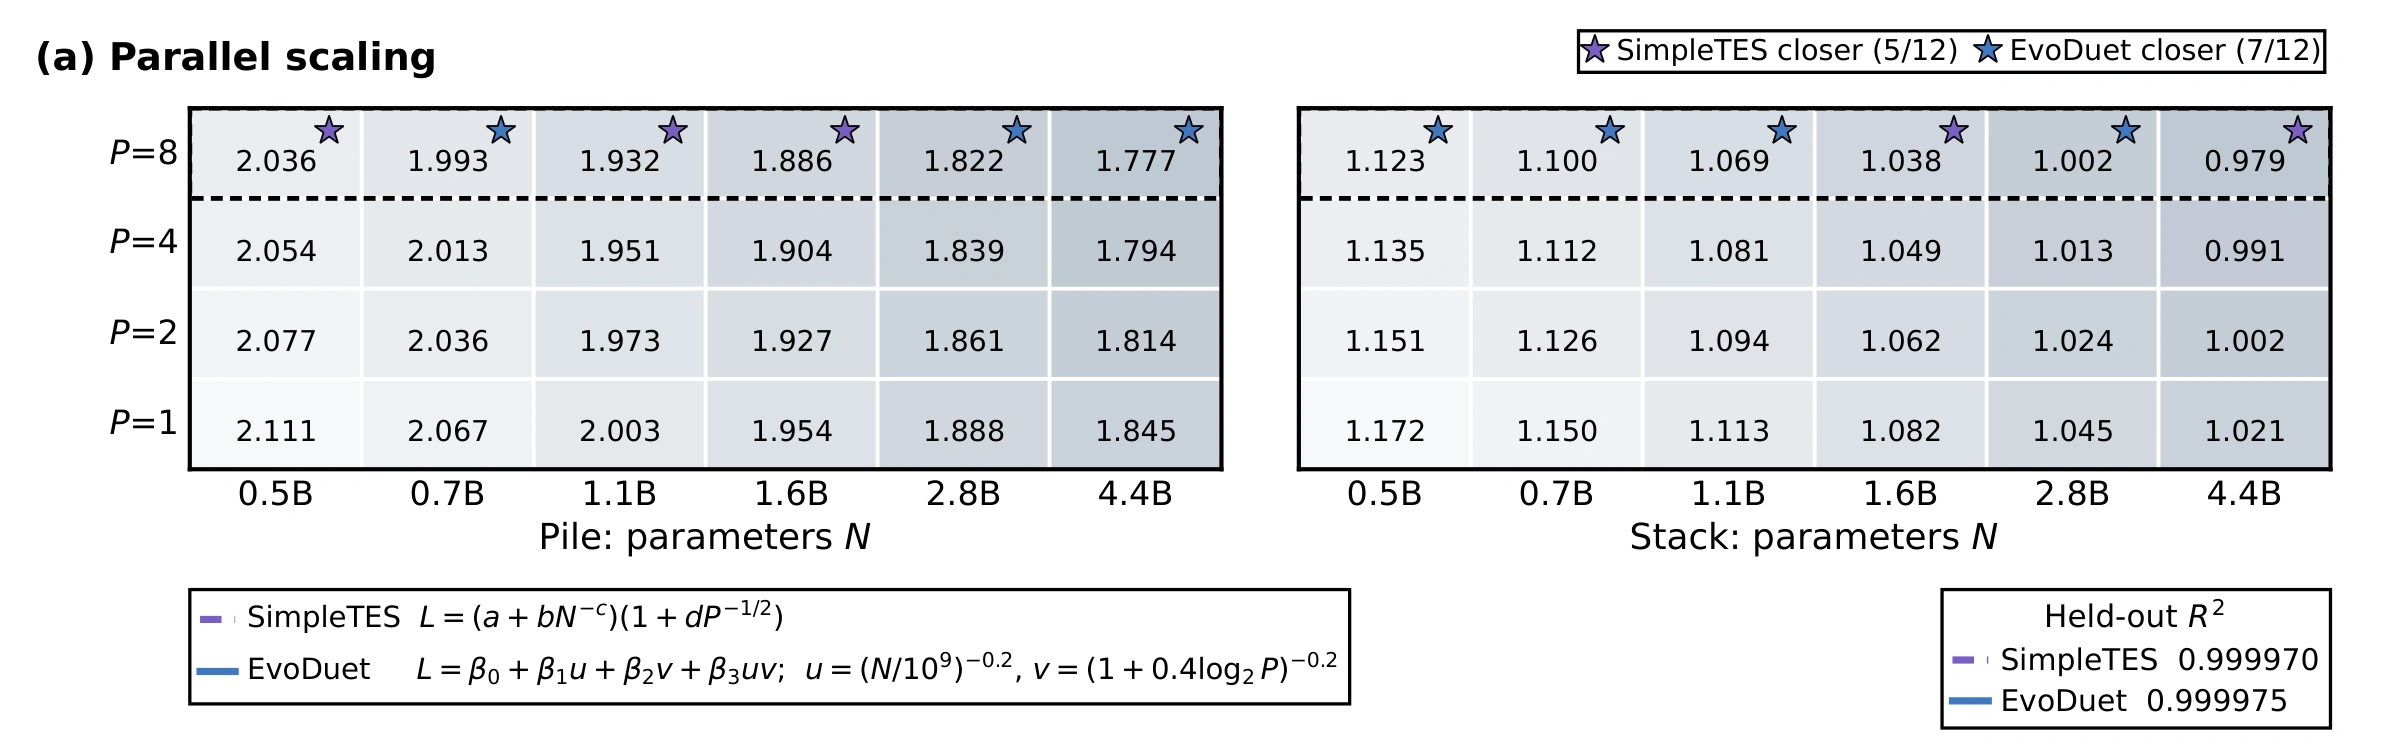
Parallel Scaling Law for language models (Chen et al., 2025):
Effective parameter count scales as N_eff = N * (1 + 0.4 * log2(P)).
The loss follows a 4-parameter basis with power-law exponent -0.2:
Loss(N, P) = b0 + b1 * N^(-0.2) + b2 * (1 + 0.4*log2(P))^(-0.2) + b3 * N_eff^(-0.2).
"""
import numpy as np

def _design(data_points):
    X = np.atleast_2d(np.asarray(data_points, dtype=float))
    u = np.maximum(X[:, 0] * 1e-9, 1e-6) ** -0.2
    v = (1.0 + 0.4 * np.log2(np.maximum(X[:, 1], 1.0))) ** -0.2
    return np.column_stack([np.ones(len(X)), u, v, u * v])

def scaling_law_func(data_points, params):
    A = _design(data_points)
    p = np.asarray(params, dtype=float)
    if p.ndim == 1:
        return A @ p
    return A @ (p.T if p.shape[-1] == 4 else p)

def fit_scaling_law(data_points, loss_values):
    A = _design(data_points)
    y = np.asarray(loss_values, dtype=float)
    p, *_ = np.linalg.lstsq(A, y, rcond=None)
    return p.T if y.ndim > 1 else p
# EVOLVE-BLOCK-END
Requires the original benchmark harness and dependencies.
Score history 100 iterations
Score history
Best-so-far search-time score ↑ · each new best is colored by that iteration’s gate decision
RetrieveLook-UpNo-Op
Gate decisionsIterations 1–100 · Retrieve 16 · Look-Up 15 · No-Op 67
Search-time scores; the final native objective is reported above.
Run details
A fitted scientific model of how loss changes with the benchmark’s parallelism and training variables.
The reported score belongs to the archived Gemini-3.8-Flash program at iteration 2.
Recorded score: 0.9999749713681108 · reference: 0.9999696795680629 · seed: 42.
Program ID: 1aaa9988-f544-4fb4-b82f-75023249e86b
Source SHA-256: af56d55174575c4a4550f77b57940d80a86614b58bf0e466328d38044e5041bd
History SHA-256: 99259717a17ecf3edad5beafe53e9bcbd8e6b054973838eed6752cc4e8c5b7ca